

Engineers with startup d-Matrix have spent the past seven years putting together the pieces of what would become a platform of hardware and software designed to speed up AI inferencing workloads while driving down the costs. The company has been focused on inferencing since its founding in 2019, “when not many people even knew what inference was,” co-founder and chief executive officer Sid Seth said.
Since that time, the demand for faster inferencing has skyrocketed, with the rise over the past year of agentic AI tools like Anthropic’s Claude Code and the introduction of OpenClaw helping to push inferencing workloads past what GPUs like those from Nvidia and AMD can handle on their own.
“Over the last twelve months, there has been an explosion of low-latency inference across many different applications,” Seth told journalist and analysts during a briefing this week. “Now, with the arrival of cybersecurity applications, low latency tokens are in huge demand. Because of this explosion in low latency inferencing, the demand for inference has really shot off the charts.”
After seven years of development, d-Matrix, armed with more than $500 million in funding – including from Microsoft’s M12 venture arm – in June introduced its first inference accelerator platform, Corsair, which takes a memory-centric approach that executives claim can help run inferencing workloads ten times faster than Nvidia GPUs alone.
Now, Corsair is being paired with Nvidia’s “Blackwell” GPU accelerators in a rack.
The XPU tightly couples the memory, such as SRAM or 3D-RAM, with GPUs and CPUs in the same rack to accelerate the generation of tokens and reduce the associated costs. In a disaggregated environment, GPUs are best for the compute-intensive prefill phases of the inferencing workload, where context tokens are processed, while Corsair, like Nvidia’s Groq 3 LPX accelerator, is better at the decode portion, where the AI model is generating code or other kinds of responses to queries from people or other models.
Building off of its acquisition in April of the datacenter business of GigaIO, d-Matrix also rolled out its SquadRack reference design, which was built with Arista Networks, Broadcom, and Supermicro.
“Our entire approach is predicated on doing more with the capital people deploy in our compute,” Seth said. “We are able to run really, really fast compute. We do more inference with a little amount of time, and we have made a very energy-efficient solution with the memory-centric computing. That allows us to do more with less of these resources – money, time, and energy. We can hopefully, over time, alleviate the need to build out more datacenters.”
With Corsair on the market for a matter of months, d-Matrix is now talking about its follow-on, the Raptor platform, which d-Matrix detailed during the recent Hot Chips 2026 show, and has put the Lightning platform – which will feature a multi-high DRAM stack – on the roadmap. Raptor, which will tape out by the end of the year and be released in the fourth quarter of 2027, includes a 3D-RAM accelerator that features a 4 nanometer compute die manufactured by Taiwan Semiconductor Manufacturing Co fused atop a custom DRAM die at a 36-micron pitch that will deliver 100 TB/sec of bandwidth.
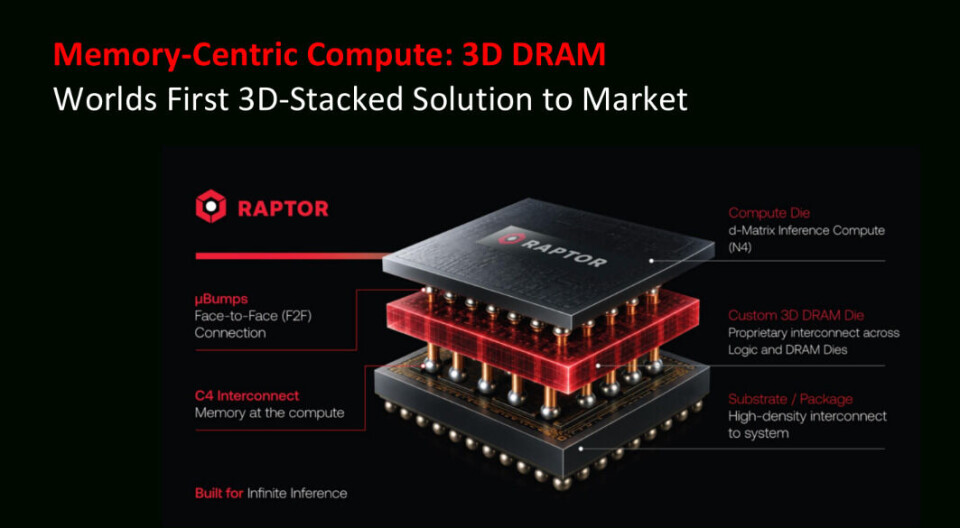
With Raptor, D-Matrix uses a variant of the chip-on-wafer package that’s used now for HBM packaging. It will combine a DRAM memory chip and a SRAM compute chip.
A new partnership with Nvidia will help d-Matrix extend its reach deeper into enterprise and HPC datacenters as well as AI labs, hyperscalers, the big cloud builders, and the neocloud upstarts. The partnership, announced Thursday, will make d-Matrix’s Raptor XPU platform available through Nvidia’s MGX reference architecture, deployed as part of Nvidia’s AI factory offering. Seth said Raptor needs a “house to put it in,” and that while building its own liquid-cooled rack was an option, Nvidia offers an existing ecosystem.
“This is truly the fastest way we feel of getting this amazing path-breaking technology that we are building at D-Matrix into the market with quick scale, with a robust supply chain to back it up and with a partner who is deployed in every datacenter across the world,” he said.
The partnership will also include future versions of d-Matrix’s XPUs, including Lightning.
Nvidia’s AI factory business is expanding rapidly. In announcing the company Q2 2027 numbers, chief financial officer and executive vice president Colette Kress said the revenue opportunity for the AI factory platform has grown from about $18 billion per gigawatt since the “Grace-Hopper” rackscale systems in 2022 to $40 billion per gigawatt now with the forthcoming “Vera-Rubin systems. That’s the opportunity d-Matrix is signing up for.
Key to d-Matrix’s plans is NVLink and NVSwitch, Nvidia’s high-speed interconnect for coherently linking GPUs, CPUs, and other accelerators to its rack-scale MGX architecture, which includes the Vera CPUs, the Rubin GPUs, Bluefield-4 DPUs, Spectrum-X Ethernet networking, and ConnectX-9 SuperNICs.
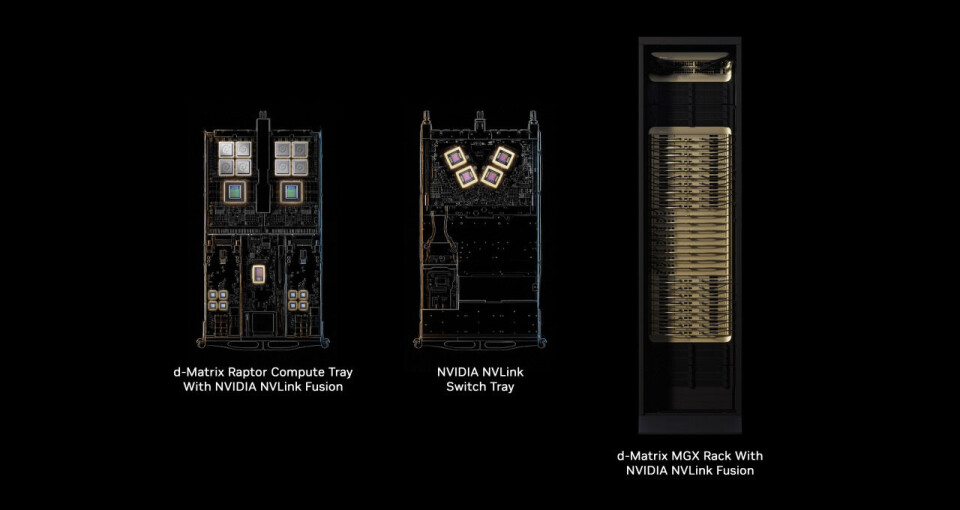
d-Matrix will use the same NVLink compute tray, seen on the left below, but rather than Vera-Rubin chips, it will house Raptor XPUs as well as Nvidia’s Vera CPUs and Bluefield DPUs, and will use ConnectX and Spectrum-X networking for scale out. It will plug into the liquid-cooled NVL144 MGX rack, on the right, and d-Matrix will use the NVLink switch tray. The rack itself will hold 144 Raptor XPUs.
The rack also will feature 2.3 TB of 3D-stack DRAM fast memory at running at 100 TB/sec inside each card with an aggregate memory bandwidth of 7.2 Petabytes per second in a single rack. There also is the option of using the Raptor rack as a companion to Nvidia racks running Vera-Rubin GPUs.
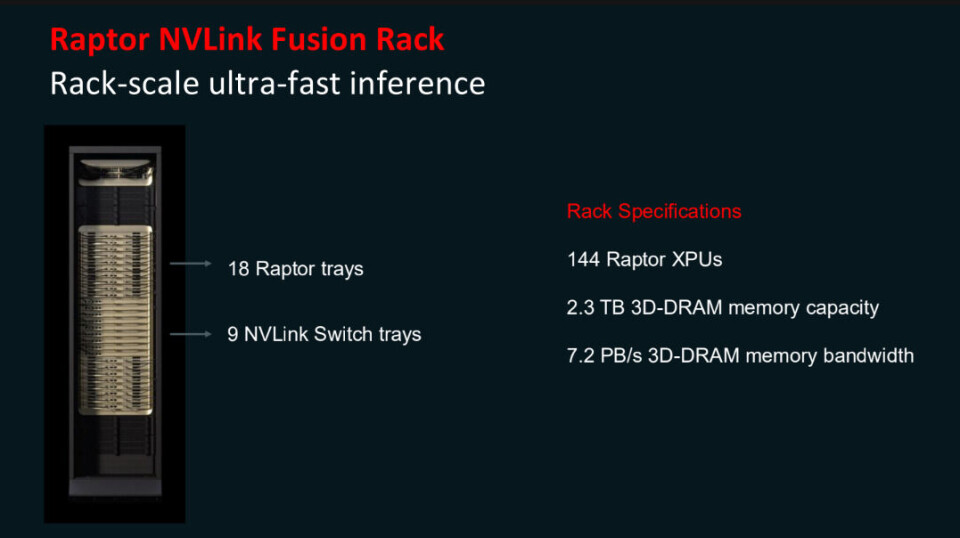
“The beauty of this solution is we take the Raptor trays, plug them into the same NVL144 MGX rack architecture, which is widely deployed across many datacenters, and we get instant access to those datacenters,” Seth said.
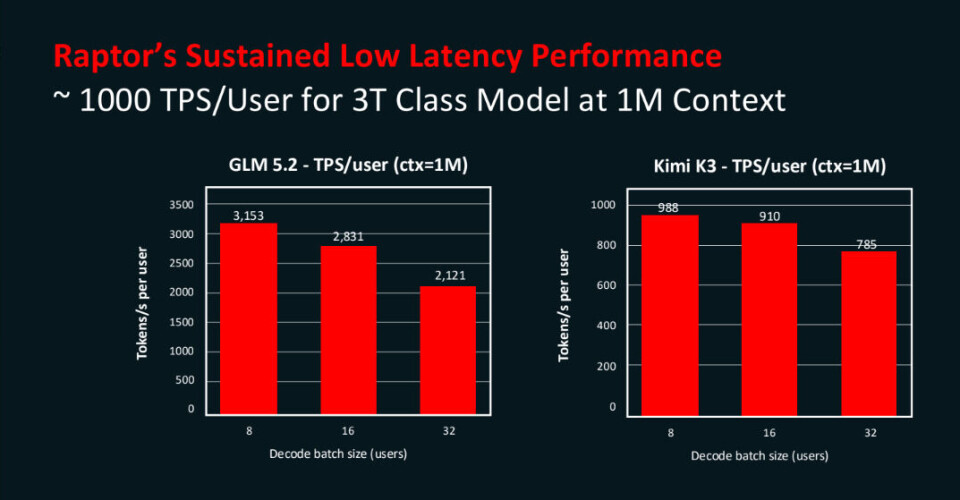
At Hot Chips, d-Matrix showed the results (below) of two AI models – Z.ai’s GLM 5.2 and Moonshot AI’s Kimi K3 – running on a rack of Raptor chips. With GLM 5.2, d-Matrix got about 3,000 tokens per second per user of performance, with the Kimi model reaching 1,000 tokens per second per user. Seth noted that the vendor can scale this across eight racks.
Jesse Clayton, principal product marketing manager for Nvidia’s Data Center GPU business, said the d-Matrix partnership illustrates Nvidia’s architectural approach, offering a platform that he called “completely fungible” and “vertically integrated, but horizontally open.” Vendors essentially can use as much of Nvidia’s technology stack – which also includes Groq 3 LPX accelerator rack – as they want, while plugging in their own offerings. NVLink Fusion ports open the platform to other silicon.
We will be doing a deeper dive into the Corsair and Raptor architectures shortly. Stay tuned.
